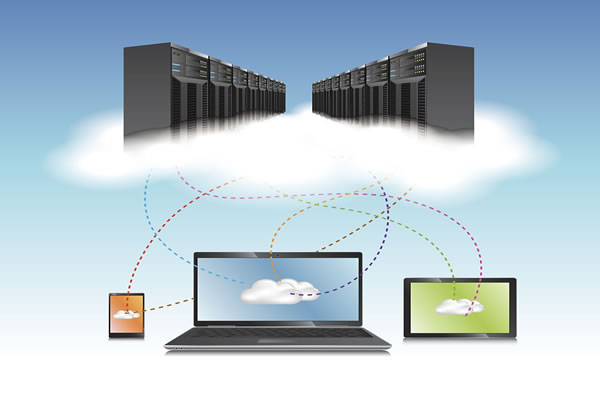
This article focuses on the theme "Migration Case Study: Roadmap for Scalable Cloud Servers in the US from Standalone to Distributed," providing a set of practical migration ideas. This article balances technical feasibility with business continuity, suitable for services within the United States or for users in the US, gradually evolving a standalone architecture into a scalable, fault-tolerant distributed system.
Project Background and Driving Factors
Many applications targeting the US region initially deployed as standalone or single-instance deployments for rapid launch, but as traffic and data increased, single-server bottlenecks, availability, and compliance risks gradually emerged. This migration case focuses on enhancing scalability, reducing the risk of single points of failure, and meeting local compliance and latency requirements, laying the foundation for subsequent distributed evolution.
Clearly define goals and quantifiable indicators
Before migration, clear goals should be defined, such as achieving over 99.95% availability, horizontal scalability supporting triple peak traffic, and keeping RPO and RTO within acceptable ranges. Set migration success standards through key business metrics (response latency, throughput, error rate) to ensure alignment between engineering and product team goals.
Current Status Assessment: Components, Dependencies, and Bottlenecks
Conduct a comprehensive assessment of the existing single-machine environment, including applications, databases, storage, external dependencies, network topology, and operations and maintenance processes. Identify CPU, memory, IO, and network bottlenecks, as well as implicit state management points and third-party service dependencies, and prioritize distributed splitting and data migration.
Migration strategy selection: gradual breakdown and deployment model
Recommended phased migration: start with horizontal splitting of stateless services, using containerization or process isolation, then gradually introduce microservices and service grids. Standalone instances can run in parallel with new distributed services, reducing risks through traffic splitting, grayscale releases, and API adapters, ensuring a smooth transition.
Key pointsof network topology and security design
When designing networks on scalable cloud servers in the United States, private subnets, inter-network routing, and cross-zone connectivity should be planned, and load balancing and edge acceleration should be used reasonably. On the security side, it is necessary to achieve least privilege, encrypted transmission, WAF, and log auditing to meet data sovereignty and compliance requirements, while ensuring disaster recovery across Availability Zones.
Database migration and consistency solutions
Databases are key migration points; strategies such as database and table partitioning, read-write separation, and asynchronous replication are recommended. For scenarios requiring strong consistency, dual-write or transaction middleware can be used, with online synchronization achieved through Change Data Capture (CDC) to ensure data integrity and rollback.
Automated deployment and CI/CD practices
Automated pipelines are established to ensure repeatable deployment and rapid rollback. CI/CD includes code building, image management, automated testing, and blue-green/grayscale releases. Achieve environmental consistency through Infrastructure as Code (IaC), reduce risks from manual changes, and improve iteration speed and stability.
Monitoring, alerting, and elastic scaling strategies
Distributed systems require fine-grained monitoring, including application performance, database metrics, network latency, and business metrics. Combined with automatic elastic scaling strategies (based on metrics or forecasts) to achieve on-demand scaling, while designing multi-level alerts and self-healing processes to quickly locate and mitigate anomalies, ensuring service availability.
Testing, rehearsal, and rollback mechanisms
Continuous integration testing, performance testing, and chaos experiments are conducted during migration to verify system robustness. Establish clear rollback plans and data rollback processes to ensure rapid recovery to standalone or legacy architectures when serious issues are found, minimizing business losses and user impact.
Conclusion and implementation recommendations
Breaking down the migration of "US scalable cloud servers from single-machine to distributed" into clear phases helps control risks and ensure smooth evolution. It is recommended to first address stateless services and network design, then advance database and state migration, gradually switching traffic by combining automation and monitoring capabilities, ultimately achieving a highly available, scalable, and operable distributed architecture.
- Latest articles
- Popular tags
-
Recommendations For Cloud Servers That Require US IP And Their Usage Scenarios
This article recommends suitable cloud servers that require US IP and analyzes their usage scenarios. -

Application Scenarios And Cases Of Independent Ip Of American Cloud Servers
explore the various application scenarios and cases of independent ip of american cloud servers, so that you can understand its advantages and practicality in different fields. -

Best Practices For Playing American Games With VPS And Cloud Gaming Platforms
For users who want to play games in the United States, this article introduces the best practices for VPS and cloud gaming platforms to play American games: practical suggestions such as VPS selection, network and protocol optimization, security configuration, and troubleshooting.